
Introduction
Keeping an application running smoothly requires more than writing and testing code. Teams must understand what happens after deployment, watch system behavior, respond to failures, and improve weak areas.
Site Reliability Engineering gives engineers a practical way to manage these responsibilities. SRE combines software development, infrastructure, monitoring, automation, incident response, and reliability measurement.
Learners who study SRE can develop a broader understanding of production systems. They learn how to measure service performance, investigate problems, manage operational tasks, and build processes that support dependable services.
SRESchool.in covers important areas such as SRE Training, SRE Certification, SRE Course concepts, SRE Tutorials, SRE Tools, observability, monitoring, automation, cloud reliability, and incident management.
What Is Site Reliability Engineering and Why Does It Matter?
Site Reliability Engineering uses engineering methods to improve the reliability of software services and infrastructure.
Instead of relying on assumptions, SRE teams collect useful information about system behavior. They use that information to understand problems and make practical improvements.
Teams may measure:
- Service availability
- Request success rates
- Response times
- Error rates
- Traffic volume
- Resource usage
- Recovery time
- Capacity
Consider an application that becomes slow during heavy traffic. Engineers can compare traffic levels, application metrics, database performance, infrastructure resources, and recent changes.
This investigation helps the team find possible causes and choose an appropriate response.
SRE also encourages teams to learn from incidents. After restoring a service, engineers can review what happened and improve the system or process.
What Can You Learn Through SRE Training?
SRE Training can introduce learners to the technical foundation needed for production reliability.
A practical learning program may include:
- Linux
- Networking
- Programming fundamentals
- Scripting
- Version control
- Cloud infrastructure
- Monitoring
- Metrics
- Logging
- Alerting
- Observability
- SLOs
- SLIs
- SLAs
- Error budgets
- Incident response
- Automation
- Capacity planning
- Troubleshooting
- Distributed systems
Learners can combine these topics through practical exercises.
For example, they can deploy a simple application, monitor its health, create an alert, inspect logs after a failure, and document the steps they followed to restore the service.
This practice helps learners understand how individual SRE concepts work together.
What Is SRE Certification and Why Do Professionals Consider It?
SRE Certification can give professionals a structured framework for studying Site Reliability Engineering.
Certification providers can create different syllabi, prerequisites, examinations, and assessment methods. Recognition can also vary between organizations and providers.
Certification programs may include:
- Reliability principles
- Monitoring
- Service objectives
- Incident response
- Automation
- Cloud operations
- Production systems
- Reliability measurement
Professionals may use certification to organize their learning or demonstrate knowledge of a specific curriculum.
However, practical SRE work requires more than certification knowledge. Engineers need to troubleshoot systems, interpret technical information, work with infrastructure, respond to incidents, and apply reliability practices.
Hands-on experience can complement certification study.
How to Choose an SRE Course
The right SRE Course depends on the learner’s background and goals.
Beginners can look for courses that start with Linux, networking, infrastructure, and monitoring. Experienced professionals may prefer deeper material about observability, distributed systems, automation, and production architecture.
Before choosing a course, learners can examine:
- Course syllabus
- Learning objectives
- Prerequisites
- SRE fundamentals
- Monitoring
- Observability
- SLOs and SLIs
- Error budgets
- Incident management
- Automation
- Cloud reliability
- Troubleshooting
- Practical projects
A clear syllabus helps learners understand what they will study.
Practical assignments can also add value because SRE requires problem-solving and system investigation.
What Is Site Reliability Engineering Training?
Site Reliability Engineering Training helps learners connect reliability concepts with real engineering situations.
Imagine a service that starts producing errors shortly after a deployment.
An engineer can investigate the event by checking:
- The time when errors began.
- Recent software changes.
- Request volume.
- Application logs.
- Error metrics.
- Infrastructure resources.
- Dependent services.
The engineer can compare this information and determine the next appropriate action.
Training can also cover deployment reliability, monitoring, incident response, capacity planning, automation, cloud infrastructure, and recovery processes.
The main purpose involves building practical thinking skills rather than simply memorizing technical definitions.
Understanding Site Reliability Engineering Certification
Site Reliability Engineering Certification can provide a structured path through important SRE subjects.
Programs may cover:
- Reliability concepts
- Monitoring
- Service-level objectives
- Incident response
- Automation
- Production operations
- Cloud systems
Learners should examine the specific certification syllabus and assessment rules before selecting a program.
A certificate can show that a learner completed a particular assessment or curriculum. Practical engineering ability grows through application.
For example, someone can study incident response in theory and then practice a simulated service failure to understand how communication, investigation, recovery, and documentation work together.
How SRE Tutorials Can Help You Learn
SRE Tutorials can make technical subjects easier by dividing them into smaller lessons.
A learner can start with a basic topic such as monitoring and gradually move toward observability, alerting, troubleshooting, and incident response.
Tutorials can explain:
- How metrics describe system behavior
- How logs help engineers investigate errors
- How traces follow requests
- How alerts identify important conditions
- How SLOs create reliability targets
- How error budgets support reliability discussions
- How automation reduces repetitive work
- How teams respond to incidents
Simple examples can make difficult concepts easier to understand.
A tutorial about SLIs, for instance, can use response time as a basic measurement and then explain how a team can create an SLO around that measurement.
Understanding SRE Tools and Their Uses
SRE Tools help engineers monitor systems, investigate failures, manage infrastructure, and automate operational work.
Different categories serve different purposes:
- Monitoring tools — Track application and infrastructure health.
- Metrics tools — Collect numerical measurements.
- Logging platforms — Store and search system events.
- Tracing tools — Follow requests across multiple services.
- Alerting tools — Notify engineers about important conditions.
- Incident management tools — Organize response activities.
- Infrastructure tools — Help manage technical resources.
- Infrastructure-as-code tools — Define infrastructure through configuration.
- Deployment tools — Support software releases.
- Observability platforms — Bring multiple system signals together.
Organizations should choose tools according to their architecture, technology stack, operational requirements, team skills, and budget.
Learners should focus on understanding the purpose of each category rather than memorizing a long list of products.
What Are SRE Best Practices?
SRE Best Practices help teams create practical habits around reliability.
Teams can focus on:
- Define measurable reliability goals.
- Select meaningful SLIs.
- Set suitable SLOs.
- Use error budgets when appropriate.
- Build useful alerts.
- Collect important metrics and logs.
- Add tracing for complex systems.
- Automate repetitive processes.
- Prepare incident runbooks.
- Practice recovery procedures.
- Review incidents after service restoration.
- Plan system capacity.
- Improve deployment safety.
- Address repeated failure patterns.
Teams should adapt these practices to their own environments.
A small internal service may need a simpler approach than a platform that connects dozens of production services.
The important point is to use practices that give engineers useful information and help them take practical action.
What Does an SRE Engineer Do?
An SRE Engineer helps maintain reliable production systems.
The work can include:
- Monitoring applications
- Investigating incidents
- Troubleshooting failures
- Reviewing metrics
- Examining logs
- Improving observability
- Writing automation
- Managing infrastructure
- Supporting deployments
- Planning capacity
- Improving recovery
- Reviewing reliability trends
SRE Engineers can work closely with developers, platform teams, cloud engineers, security teams, and operations professionals.
Responsibilities vary between organizations.
Some teams may expect more software development from SRE Engineers. Other teams may place greater emphasis on cloud infrastructure, monitoring, automation, or incident management.
A broad technical foundation can help engineers work across these areas.
Understanding SLOs, SLIs, SLAs, and Error Budgets
SRE uses these terms to describe reliability in measurable ways.
SLI — Service Level Indicator
An SLI measures actual service behavior.
Examples include:
- Response time
- Availability
- Request success rate
- Error rate
SLO — Service Level Objective
An SLO sets a target for an SLI.
For example, a team can define a target for successful requests over a selected period.
SLA — Service Level Agreement
An SLA describes formal expectations between parties. It can define commitments, responsibilities, and service conditions.
Error Budget
An error budget represents the amount of unreliability that fits within a selected SLO.
These concepts help teams turn broad goals into measurable reliability discussions.
Teams should select targets according to their service, users, technical architecture, and business requirements. No single target works for every system.
How Monitoring and Observability Help SRE Teams
Monitoring helps teams identify changes in system behavior.
Engineers may track:
- Request volume
- Error rates
- Response time
- CPU usage
- Memory
- Storage
- Availability
- Network activity
Observability helps engineers investigate the reasons behind those changes.
Teams commonly use three important signals:
Metrics provide numerical measurements.
Logs provide records of application and system events.
Traces show how requests move through different services.
Suppose users report slow responses. Metrics may reveal higher latency. Logs may show errors in a backend component. Traces may identify the service that adds the most delay.
Engineers can combine these signals to narrow down the problem.
Good observability also helps teams create more useful alerts and reduce unnecessary noise.
Understanding Incident Management and Incident Response
Incident management helps teams organize their response when a production service experiences a serious problem.
A response process can include:
- Detect the issue.
- Confirm the impact.
- Identify the appropriate responders.
- Collect useful evidence.
- Investigate possible causes.
- Reduce the immediate impact.
- Restore the service.
- Communicate important information.
- Record the incident.
- Identify improvement actions.
Teams can prepare runbooks, escalation procedures, and communication plans before incidents occur.
After recovery, a postmortem can help engineers understand the event.
A useful review examines technical causes, contributing conditions, process gaps, and possible improvements. Teams should use the process to learn rather than simply assign blame.
How Automation Can Reduce Repeated Work
SRE teams often automate tasks that follow predictable steps.
Examples include:
- Infrastructure provisioning
- Deployment checks
- Health checks
- Configuration updates
- Backup validation
- Resource cleanup
- Routine maintenance
- Diagnostic tasks
Automation can reduce repetitive work and improve consistency.
Before automating a task, engineers should understand how the process works and what can go wrong.
Good automation also needs suitable testing, logging, monitoring, access controls, and recovery options.
The goal is not to automate every task. Engineers should automate processes where predictable behavior and clear benefits make automation useful.
Understanding Cloud Reliability and Distributed Systems
Cloud services often depend on many connected components.
An application may use:
- Compute resources
- Databases
- Storage
- Networks
- APIs
- Message queues
- Identity services
- External providers
One component can affect another.
For example, an application may have healthy servers while a slow database causes users to experience longer response times.
Distributed systems make troubleshooting harder because one request can travel through several services.
SRE teams therefore need to understand:
- Service dependencies
- Scaling
- Resource usage
- Failure handling
- Recovery
- Network behavior
- Capacity
- Observability
This broader understanding helps engineers investigate problems across the complete service.
How Kubernetes and Terraform Can Support SRE Work
Kubernetes helps organizations manage containerized workloads.
Teams can use it for:
- Workload scheduling
- Service management
- Container orchestration
- Scaling
- Desired-state management
Kubernetes can support certain production architectures, but teams should evaluate whether its capabilities match their needs.
Terraform supports infrastructure as code.
Engineers can describe infrastructure through configuration and manage changes in a repeatable way.
Terraform can support:
- Infrastructure reviews
- Repeatable environments
- Configuration tracking
- Reduced manual infrastructure work
Teams should choose Kubernetes, Terraform, or other technologies according to their architecture, operational needs, technical skills, and existing systems.
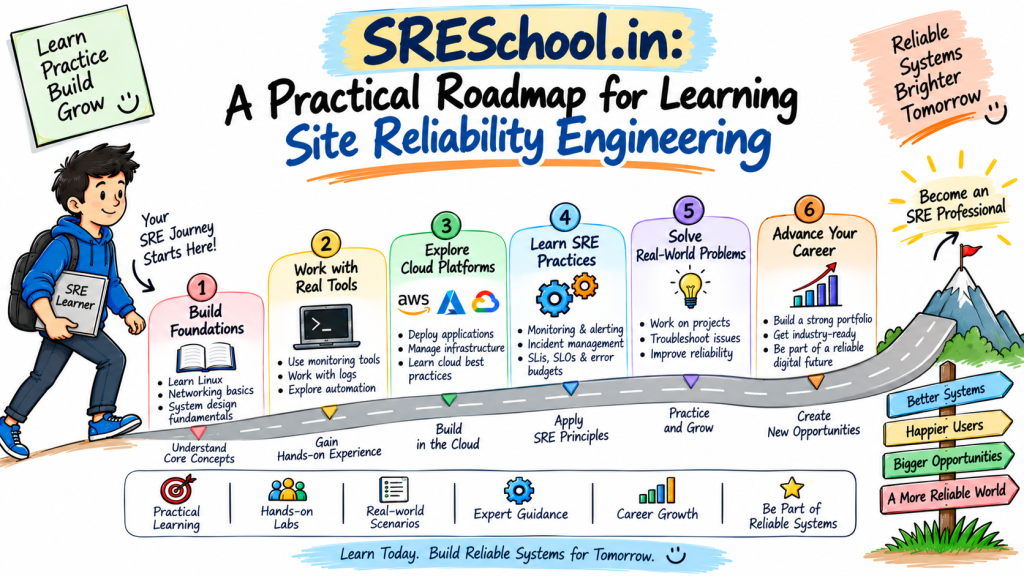
How to Build a Simple SRE Learning Path
Learners can build SRE skills gradually.
Begin with technical foundations
Study Linux, networking, scripting, version control, and basic programming.
Understand infrastructure
Learn about servers, storage, networks, cloud resources, and deployment processes.
Study monitoring
Practice metrics, logs, dashboards, alerts, and basic troubleshooting.
Explore observability
Learn how metrics, logs, and traces help engineers understand complex systems.
Learn reliability concepts
Study SLIs, SLOs, SLAs, error budgets, incident response, and capacity planning.
Practice automation
Work with scripting, infrastructure as code, deployment automation, and routine operations.
Explore advanced systems
Study Kubernetes, distributed systems, scaling, service dependencies, and recovery.
Build practical projects
Create a small service, add monitoring, introduce controlled failures, investigate the results, and improve the system.
This progression helps learners build knowledge in manageable steps.
Understanding SRE Training in India
SRE Training in India can help students and professionals explore Site Reliability Engineering, cloud infrastructure, automation, monitoring, and production operations.
When comparing programs, learners can check whether the curriculum covers:
- SRE fundamentals
- Linux
- Networking
- Cloud platforms
- Monitoring
- Observability
- Incident response
- SLOs and SLIs
- Automation
- Troubleshooting
- Infrastructure as code
- Container technologies
Learners should also examine the practical work, prerequisites, teaching format, course structure, and learning objectives.
Learning outcomes depend on many factors, including prior knowledge, practice, course content, technical background, and professional responsibilities.
Training can support skill development, but it cannot guarantee a specific job, salary, promotion, or career outcome.
How SRESchool.in Supports SRE Learning
SRESchool.in focuses on subjects related to Site Reliability Engineering and production reliability.
The learning areas include SRE Training, SRE Certification, SRE Course concepts, SRE Tutorials, SRE Tools, monitoring, observability, automation, cloud reliability, and incident management.
These topics can help learners understand the different building blocks of SRE.
Learners can strengthen their knowledge through practical work.
They can create a small application, monitor system behavior, configure alerts, inspect logs, test controlled failures, automate repeated tasks, and document recovery steps.
This approach helps learners connect separate lessons into a practical reliability workflow.
Why Learning SRE Is Becoming More Useful
Production environments often combine applications, infrastructure, databases, networks, cloud resources, containers, APIs, and external services.
Engineers need to understand how these components interact.
SRE learning can develop knowledge in:
- System reliability
- Cloud operations
- Monitoring
- Observability
- Automation
- Incident management
- Troubleshooting
- Capacity planning
- Distributed systems
- Production operations
These skills can complement work in DevOps, cloud engineering, platform engineering, infrastructure, and software development.
Their usefulness depends on the responsibilities, technology stack, and operating model of each organization.
Frequently Asked Questions About SRESchool.in
1. What does SRESchool.in cover?
SRESchool.in covers Site Reliability Engineering subjects such as SRE Training, SRE Certification, SRE Course concepts, SRE Tutorials, SRE Tools, monitoring, observability, automation, and incident management.
2. What can learners study through SRE Training?
Learners can study reliability principles, monitoring, observability, SLOs, SLIs, error budgets, incident response, automation, cloud reliability, troubleshooting, and production operations.
3. Can a beginner start an SRE learning path?
Yes. A beginner can start with Linux, networking, programming basics, version control, cloud fundamentals, and system administration.
4. What does SRE Certification demonstrate?
SRE Certification can demonstrate knowledge of a particular certification curriculum. Requirements, assessment methods, and recognition vary by provider and organization.
5. What does an SRE Engineer work on?
An SRE Engineer may work on monitoring, troubleshooting, automation, infrastructure, incidents, deployments, capacity, system performance, and reliability improvements.
6. What are the major SRE Tool categories?
Major categories include monitoring, metrics, logging, tracing, alerting, incident management, infrastructure, deployment, observability, and infrastructure as code.
7. How does an SLI differ from an SLO?
An SLI measures actual service behavior, while an SLO defines a target for that measurement.
8. Why do teams use error budgets?
Error budgets help teams understand the amount of unreliability that fits within an SLO and support discussions about reliability work.
9. Does an SRE Engineer always need Kubernetes?
No. Kubernetes can help teams manage containerized workloads, but organizations should decide based on their architecture and operational requirements.
10. What practical activities can help learners develop SRE skills?
Learners can build small services, monitor them, create alerts, inspect logs, introduce controlled failures, automate routine tasks, and practice incident recovery.
Final Thoughts
Dependable production systems require steady engineering work. Teams need clear measurements, useful monitoring, sensible automation, planned incident response, and regular system improvement.
Site Reliability Engineering connects these activities and helps engineers understand both software and the environments where software runs.
Learners can start with technical foundations and gradually develop skills in monitoring, observability, SLOs, incident response, automation, cloud reliability, Kubernetes, infrastructure as code, and distributed systems.
SRESchool.in provides a focused learning path around these SRE subjects. Learners can deepen their understanding by combining structured study with projects, controlled experiments, troubleshooting exercises, and hands-on practice.

